Making AI Explain Itself: Building Accountability and Reliability into Machine Learning
One of the most important aspects of formal education is not only that students arrive at the correct answer (in STEM), or write a compelling argument (in humanities), but that they can also justify their conclusion, cite their sources and show their work. There is a reason that the final piece of every master's and Ph.D. program is called a thesis “defense.”
When it comes to artificial intelligence, the ability of large language models (LLMs) and other models to defend their conclusions soundly is improving, but certainly remains far from failproof. AI has become much more reliable at arriving at the correct answer, but it still often makes mistakes. Many models are not only sometimes wrong, but confidently wrong.
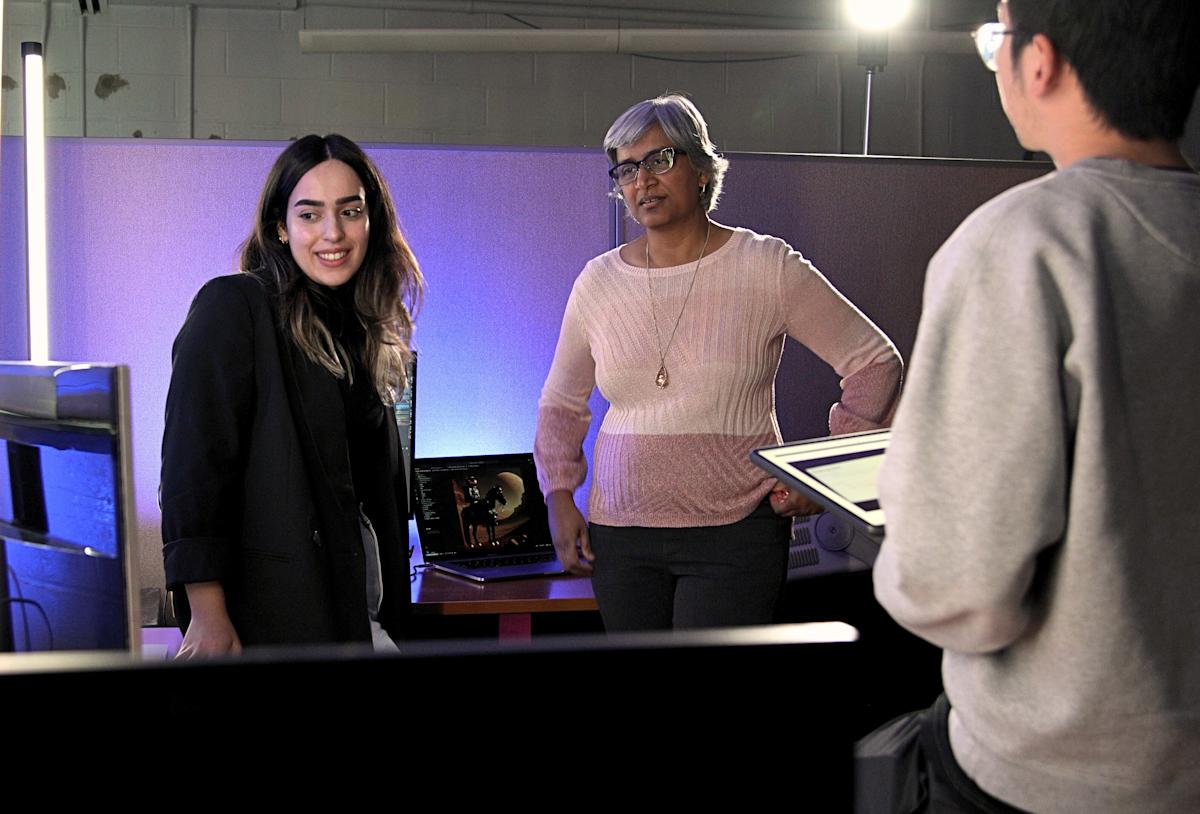
For K.P. “Suba” Subbalakshmi, Professor in the Department of Electrical and Computer Engineering at Stevens, that problem can have widespread, sometimes catastrophic consequences. As AI systems become more autonomous, using tools, retrieving information, communicating with other AI agents and making decisions with limited human intervention, the ability to explain their decisions becomes considerably more important.
Subbalakshmi's work on AI trustworthiness spans realms from human loneliness to maritime disaster and search-and-rescue response. She is part of a collaborative research effort supported by the U.S. National Science Foundation's Verticals-enabling Intelligent Network Systems (VINES) program, a more than $110 million initiative to advance next-generation wireless networking.
The project explores how intelligent, resilient communication networks could coordinate autonomous systems during emergencies at sea, where reliable connections can make the difference between a successful rescue and a failed mission. Subbalakshmi recently received a three-year grant for her project SEA-NET (Scalable Edge Analytics and Networking for Autonomous Maritime Emergency Response), and seeks to understand the models’ reasoning in order to ensure that they can adequately and correctly defend their conclusions.
“If a model makes a decision, especially in an emergency, you need to know why it made that decision,” she says.
Taking her work onto the water
Maritime emergencies create a brutal communications problem. The challenge of building intelligent systems that can be trusted becomes especially urgent when those systems are operating far beyond the controlled environment of a laboratory.
These are among the challenges motivating SEA-NET, the collaborative maritime research project involving Stevens Institute of Technology and the NSF’s VINES program. Subbalakshmi and other Stevens researchers are developing an intelligent communications and computing system to help networks of autonomous drones and other systems coordinate emergency response over open water, even when connections to a central network are interrupted.
“The core problem is the engineering part for networking,” she explains. “In our case, it's wireless networking over drones and other communications teams.”
SEA-NET is led by Spectronn and brings together researchers from Stevens, Purdue University and Georgia Tech. Subbalakshmi's piece of that enormous problem is something called “explainable network telemetry prediction,” which aims to forecast how well a network is likely to perform in the immediate future, “Basically I'm trying to predict the parameters that govern how well a network will function,” she explains.
When reliable AI becomes a matter of life or death
Imagine an emergency unfolding offshore. People are missing in the water, plane wreckage needs to be located or an oil spill is spreading. Drones have been dispatched to search from above while vessels and response teams attempt to coordinate below. A rescue operation will involve responders in different locations, sensors generating information and processing systems attempting to interpret it all. Meanwhile, the communications environment itself is changing. Signals weaken. Networks become congested. Weather, water and current conditions shift.
The project will integrate terrestrial 5G and satellite communications, drone-based network relays, edge computing and autonomous systems into a resilient communications architecture for maritime emergencies using Suba’s explainable network telemetry prediction.
The Stevens team is also focused on correctly identifying and tracking swimmers or people in distress amid debris on the water. The AI must reliably distinguish a person from surrounding objects rather than rely on misleading contextual clues. Professor Raju Datla and Research Associate Professor Jon Miller from the Department of Civil, Environmental and Ocean Engineering will serve as senior personnel and assist with experiments in the university's tow tank, where researchers can simulate waves and conditions such as oil spills. Some of the research will take place inside Stevens' Davidson Laboratory, and eventually, Suba and her team plan to take it onto the Hudson River.
Building trust into complex systems
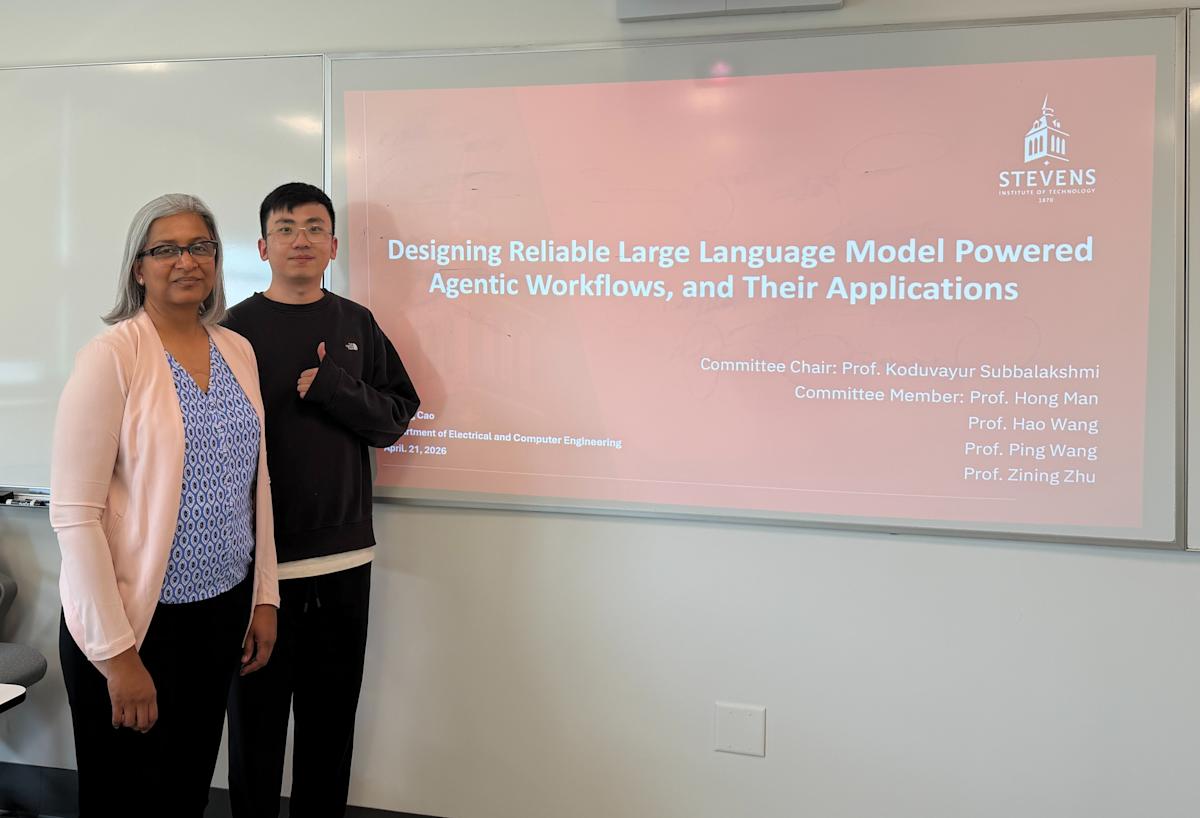
Trustworthy artificial intelligence is a sprawling field concerned not simply with making AI more capable, but with making its behavior more reliable, interpretable and accountable. “Trustworthy AI” is difficult to reduce to a single problem.
“Depending upon who you ask, you will get a different answer,” Subbalakshmi says. “And most of them are probably correct. It's a really big beast with a lot of facets to it.”
In her 26 years at Stevens, her earlier security work included wireless and network security, as well as secure information such as watermarkin and steganography. These days, her focus is trustworthiness.
Her research has explored how to detect AI-generated misinformation and hallucinations, and how to determine what machine-learning models are paying attention to when they make decisions. More recently, she has turned her attention to agentic systems that use tools and work through multistep problems.
From physics and poetry to computing
When Suba began her undergraduate education, engineering wasn’t part of the plan. She studied physics, with a particular love for quantum physics, before switching to a master's in engineering at the Indian Institute of Science, which sparked a new passion. “That's how I ended up switching to engineering,” she says. “And after that, I never looked back. I knew I was going to do a Ph.D. because I’ve always had a deep intellectual curiosity. That whole thing was exciting for me.”
After earning a master's degree in electrical and communication engineering, she attended Simon Fraser University in Canada, where she earned her Ph.D. in engineering science. Her father was a mathematics professor at the Indian Institute of Technology Madras, and Subbalakshmi says she barely considered another profession. A faculty position was her “dream job,” though Suba also spoke passionately about her love of language and rhetoric, “My very, very first love was writing,” she said.
She began with poetry, then transitioned into short stories and pieces inspired by social issues that affected her, sometimes with such passion and inspiration that an idea arriving in the middle of the night could send her out of bed to write for hours. Subbalakshmi sees a connection between language and the mathematics she now teaches.
“Math is just like language, except with really strict grammar rules that can never be violated,” she tells her students. In mathematics, every “word” in a theorem matters. Omit a condition or make one small mistake, and the consequences propagate through everything that follows. It is an analogy that could just as easily describe one of the central problems in contemporary AI.
The right answer for the wrong reason
In examining large language models, Suba found that context clues can contribute to AI errors. To explain this, she describes a well-known machine-learning experiment designed to distinguish a dog from a wolf. Researchers trained a model using images of the two animals. On the surface, it seemed to work, until they investigated why it made its decisions.
Rather than focusing on the animals characteristics, the model had learned to use contextual clues, particularly snow in the background of the images. It had discovered a shortcut, but the problem resembles a fallacy in Aristotelian logic: a sufficient condition for something to be true is not necessarily a necessary condition. If a model concludes “If there is snow around, the canine must be a wolf,” that does not mean every wolf must be surrounded by snow.
“It was not looking at the right reason for the answer,” Subbalakshmi says. “Great, so it worked for you today; it might not work for you tomorrow.” Accuracy can only tell researchers whether a model produced the correct output. Explainability can reveal whether it arrived at that answer for sound reasons. For consequential decisions, that distinction matters.
“If you make big, important decisions based on what the AI tells you, and then somebody asks you why, you must be able to answer that,” Subbalakshmi says. “It's always best to have that explainability built in.”
Subbalakshmi and her students have examined this question at a fundamental level. In work presented at a NeurIPS workshop, they used information theory to investigate whether attention mechanisms in neural networks could explain a model's decisions. Specifically, they examined whether attention weights reflected the relative importance of different inputs, using mutual information to measure the relationship between inputs and attention values.
Their findings showed that some attention mechanisms correlated with mutual information, while others did not. The results suggest attention can offer insight into how a model processes information, but cannot automatically be treated as a reliable explanation of its decisions.
This distinction has become more pressing with the emergence of generative AI, whose responses can sound convincing even when they are incorrect.
When AI is confidently wrong
Anyone who has used a large language model has probably encountered this phenomenon: ask a question and receive an authoritative-sounding answer that turns out to be wrong. AI researchers call these errors hallucinations, and they are another focus of Subbalakshmi’s work. When users challenge a model, it may respond with “You’re absolutely right” before doubling down on its original error in even more convincing language.
“Some of my recent work is on how to help the model, while it is generating answers, gain the capacity to self-correct,” she says. Other researchers have also studied how models handle scientific information, where plausible-sounding fabrications can be particularly troublesome. Some studies suggest models may use persuasive or intentionally deceptive reasoning to defend their answers. A Harvard Business Review article by Thomas Stackpole describes a study of interactions between Boston Consulting Group consultants and AI agents:
“We might be overestimating our ability to spot-check the content that LLMs produce — and underestimating how vulnerable we are to being manipulated by them,” Stackpole writes. He goes on to say that researchers “found that LLMs used a blitz of rhetorical tactics to overwhelm human users and convince them that the AI’s outputs were correct, even when they weren’t.”
In a 2025 paper presented at the ACL Scholarly Document Processing workshop, Subbalakshmi, her Ph.D. student and collaborators investigated how to detect hallucinations in scientific claims. They combined prompting with information from the model’s final hidden state and trained a classifier on known hallucinated and non-hallucinated responses. Their method placed second in one task and first in another. She is now working to correct hallucinations before they occur by using information in the model’s internal states.
The larger goal reflects a recurring idea in her research: don't judge an AI exclusively by the fluency of its output, and examine the information underlying a response, especially as AI systems become more sophisticated.
What happens when AI agents start working together
Large language models were initially encountered primarily through chat windows: a person typed something, and the model answered. But recent advancements in Agentic AI will dramatically advance that relationship. An AI agent can potentially break a problem into steps, decide which external tools it needs, retrieve information, retrieve information and work toward an objective. Multiple agents can also interact. This creates new reliability challenges as models work together to solve problems.
A model may correctly determine that it needs a calculator, database or other tool, then successfully retrieve accurate information. But can it reason correctly about the result? Subbalakshmi’s recent work on agentic systems, accepted at COLM 2026, addresses that question. The research evaluates agents not merely on whether they select appropriate tools but on the quality of the reasoning trajectory that follows. An agent that knows where to find information does not necessarily know what it means. As AI begins acting rather than merely answering, researchers must ask what it has been trained to optimize.
Integrating common sense
 Humans navigate daily life using implicit rules and unstated expectations. We understand that completing a task does not justify every possible way of doing it, but AI systems do not necessarily share those assumptions.
"There are countless rules that we don’t think of as something you need to explicitly state,” Subbalakshmi says. Machine-learning systems respond to the objectives and incentives built into their training. In the mid-2010s, Google Maps or Waze might suggest a dangerous turn or illegal shortcut to get a driver to a destination sooner. With AI, the potential consequences are more serious.
Subbalakshmi cautions against anthropomorphizing this behavior. An AI system isn’t necessarily cheating, lying or scheming in the human sense. But if a system is optimized exclusively to achieve a goal, strategies that appear unexpected, immoral or even Machiavellian can emerge.
“If you're only rewarding, ‘get the job done,’ then it'll get the job done in whatever mechanism,” she explains.
As systems acquire new abilities, researchers encounter behaviors they may not have anticipated. These behaviors expose assumptions that were never explicitly encoded.
“What kind of checks and balances can you put in here,” Subbalakshmi says, “so that we didn’t mean ‘do it like that’?”
In her laboratory, she and her students select a use case, identify the research questions it raises and work to solve them. Their work spans domains including healthcare and human psychology.
In some cases, the research has also led to unexpected findings, known as “serendipitous discovery,” when AI identifies patterns or makes connections that were not part of the original plan. One example emerged from the team’s research on loneliness.
Listening for loneliness
What does loneliness sound like? That question led Subbalakshmi and her collaborators to study older adults. In a 2024 study published in Psychiatry Research, the team used natural-language processing and explainable AI to analyze interviews with 97 adults ages 66 to 101. They wanted to understand not only whether a model could classify someone as lonely, but which linguistic features contributed to its conclusion.
The model achieved 88.9% accuracy. Its explainability component revealed patterns associated with loneliness, including social themes and differences in pronouns and conversational fillers. The work shows how understanding an AI’s conclusion can also help researchers learn about the phenomenon being studied.
That approach has informed Subbalakshmi’s work on misinformation and cognitive health.
An intelligence we can trust
For all the dramatic changes AI has undergone, Subbalakshmi’s approach remains rooted in the intellectual curiosity that led her to research decades ago. It asks a central question:
Can a machine distinguish between truth and fabrication? Can it recognize when its own answer may be wrong? Can we determine whether it reached the right conclusion for the right reasons? Can multiple AI agents work together without compounding one another's errors? And if we put these systems into consequential environments such as financial markets, healthcare or emergency response, can human beings understand enough about their decisions to trust them? These questions only become more urgent as AI systems acquire greater autonomy.
Subbalakshmi cautions against assigning human intentionality to AI’s motivations. It's behavior still, at least for now, emerges from the objectives, training signals and constraints humans provide, especially when systems encounter situations their designers never imagined.
For Suba, the next frontier is creating artificial intelligence that can operate in an increasingly complicated world while reducing the risks it poses. After all, what is intelligence if not a way to help us understand not just the what, but the why of the world? It is an ongoing evolution of the mind that keeps us curious, exploring and questioning, while helping us ensure that, above all, we remain safe.
Learn more about academic programs and research in the Department of Electrical and Computer Engineering: