Efficient Learning for Large Language Models

Department of Electrical and Computer Engineering
Location: Burchard Hall, Room 104
Speaker: Ting Hua, Assistant Research Professor, University of Notre Dame
ABSTRACT
LLMs have shown impressive capabilities, but their massive size comes at a high computational cost. Model compression aims to achieve comparable performance with a more compact model, through techniques such as quantization, pruning, knowledge distillation, and low-rank factorization. More broadly, learning itself can be viewed as a form of compression, where models encode information from data into their parameters. From this perspective, studying model compression not only improves efficiency, but also provides a useful lens for understanding how LLMs represent and utilize knowledge. In this talk, I will mainly focus on the low-rank perspective of model compression: how to decompose the weight matrices of LLMs to reduce model size and cost, and the challenges involved. I will also discuss how these low-rank ideas extend beyond compression. Finally, I will briefly share my broader research vision on how to make LLMs more efficient and more reliable, and how LLM research can help address challenges in other fields.
BIOGRAPHY
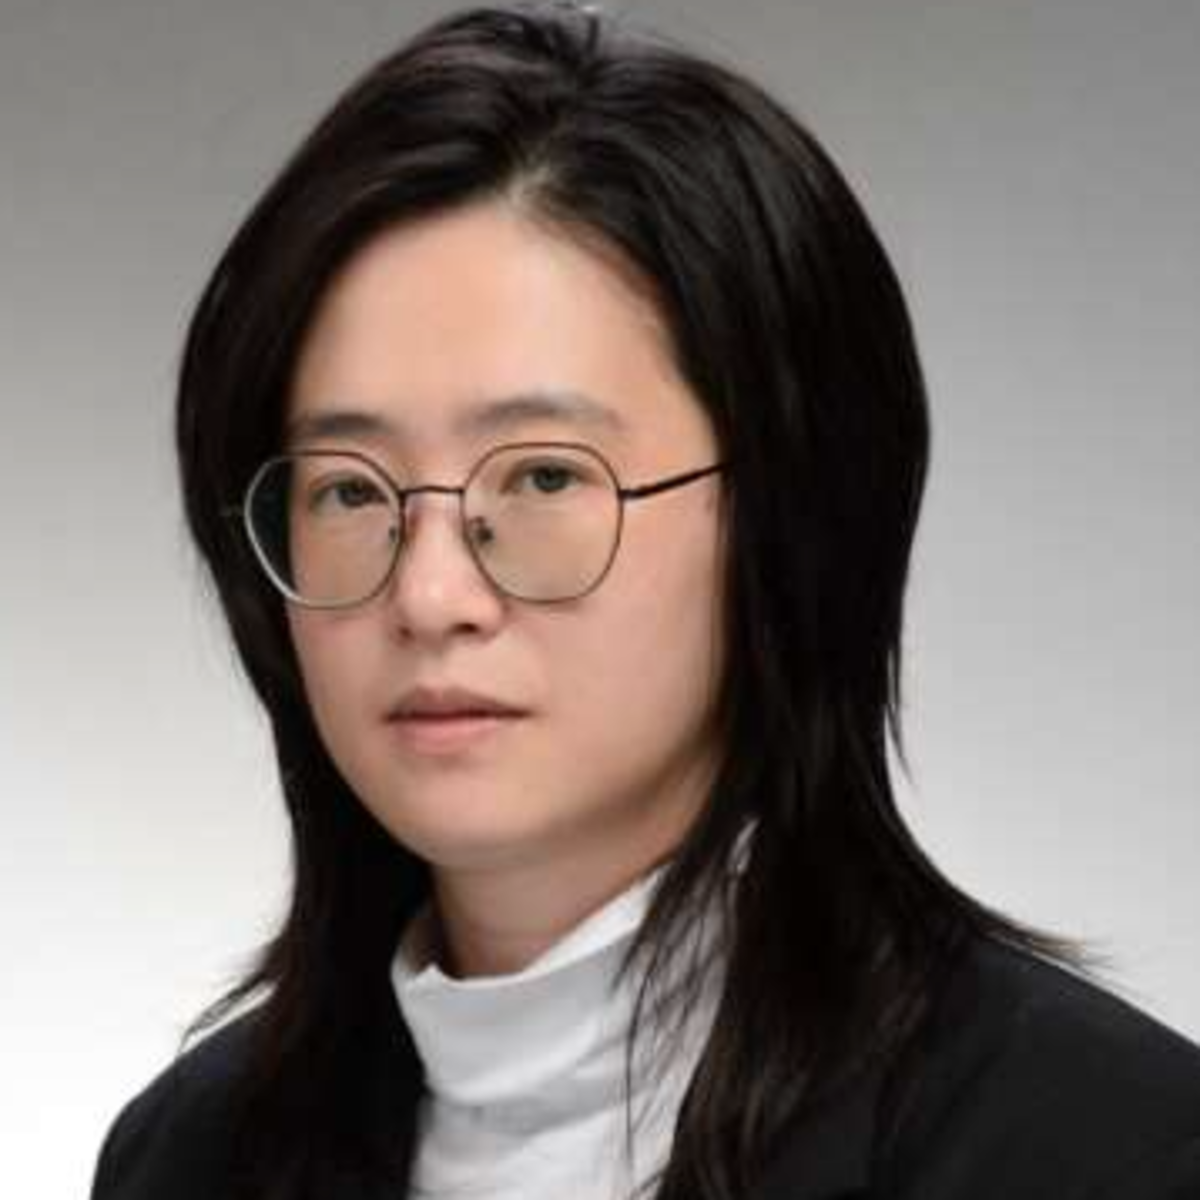
Ting Hua is an Assistant Research Professor at the University of Notre Dame. Previously, she was a Research Scientist at Samsung Research America. She received her PhD from Virginia Tech. Her research focuses on efficient learning for large language models, including model compression, efficient architectures, and continual learning. She is also interested in reinforcement learning and the learning dynamics of LLMs. More recently, her research has expanded to interdisciplinary applications of LLMs in areas such as scientific discovery, education, and social good.
Discrimination notice: Persons of all identities are invited to and included in this group. Stevens does not discriminate against any person on the basis of sex, race, religion, disability, sexual orientation, gender expression, or any other basis prohibited by law.
Photo and video notice: At any time, photography or videography may be occurring on Stevens’ campus. Resulting footage may include the image or likeness of event attendees. Such footage is Stevens’ property and may be used for Stevens’ commercial and/or noncommercial purposes. By registering for and/or attending this event, you consent and waive any claim against Stevens related to such use in any media. See Stevens' Privacy Policy for more information.